| Assignment 5: Reinforcement Learning (Value Iteration and Q-Learning) |
|
CSE 415: Introduction to Artificial Intelligence The University of Washington, Seattle, Autumn 2026 |
 |
|
Due Monday, November 23, at 11:59 PM, via
Gradescope (assignment "A5").
This assignment is worth 145 points: Part 1 (35), Part 2 (70), and Part 3, the report (40).
You may do this assignment either individually or in a partnership of two.
If you work in a partnership, you'll be turning in one set of files
for the partnership, rather than two sets of files (see What to Turn In).
You are permitted to use AI as a coding assistant in this assignment;
however, we recommend that you read
the guidelines for prompting (see the ED post about prompting guidelines under "General" here)
and do the record-keeping so that you can complete
the prompting-related part of the report.
The report also includes the general sections described on the
Assignment Reports page,
including the models and tools you used for agentic programming.
|
Contents
|
|
Introduction
This assignment not only offers an opportunity to implement the Value Iteration algorithm, but also an opportunity to see how reinforcement learning techniques can be applied to problem solving of the sort we studied earlier with state-space search. The interactions between a problem-solving agent and its problem-domain environment are modeled probabilistically using the technique of Markov Decision Processes (MDPs). Within this framework, the assignment focuses on two approaches to having the agent maximize its expected utility: (A) by a form of planning, in which we assume that the parameters of the MDP (especially the transition model T and the reward function R) are known, which takes the form of Value Iteration, and (B) by an important form of reinforcement learning, called Q-learning, in which we assume that the agent does not know the MDP parameters. The particular MDPs we are working with in this assignment are variations of a “TOH World”, meaning Towers-of-Hanoi World. We can think of an agent as trying to solve a TOH puzzle instance by wandering around in the state space that corresponds to that puzzle instance. If it solves the puzzle, it will get a big reward. Otherwise, it might get nothing, or perhaps a negative reward for wasting time. In Part 1, the agent is allowed to know the transition model and reward function. In Part 2, the agent is not given that information, but has to learn about good policies by exploring and seeing what states it can get to and how good they seem to be based on what rewards it can get and where states seem to lead to. 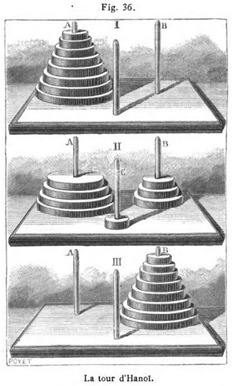
Figure 1. An early description of the problem “La Tour d’Hanoi” from the 1895 book by Edouard Lucas. Your program will determine an optimal policy for solving this puzzle, as well as compute utility values for each state of the puzzle. The starter code contains these files:
|
|
Getting Started
Download and unzip the starter code. We recommend Python 3.14 (3.10 or later is the minimum), with the Tkinter user-interface library available (it is included with the standard Python.org installers). In a command line, run python gui.py This will start up a graphical user interface, which can help you debug. You can see that some menus are provided. Some menu choices are handled by the starter code, such as setting some parameters of the MDP. However, you will need to implement the code to actually run Value Iteration and Q-learning, and some menu items will not work correctly until you implement the corresponding functions. A Note on Python Type Annotation.
Most of the starter code that you will be interacting with is annotated with types.
Python is a dynamically typed language, which makes it flexible and good for prototyping,
but any type checking happens only at runtime, so it can be hard to know what kind of
arguments a function expects, and type errors can be hard to track down.
The type annotations in the starter code are there to help you determine what’s an
appropriate input to each function. If you use an IDE with good support for static
inference, such as PyCharm, you’ll see an error if your code doesn’t type check.
For a quick introduction to type annotation, see this
cheat sheet.
If you wish to type-check your code, you can install the mypy solver_utils.py
Note that A Note on Style. With a handful of exceptions, the starter code complies with the official Python style guide PEP 8 and the Google Python Style Guide. We encourage you to follow the same conventions. If you use PyCharm, PEP 8 violations will be pointed out to you. Autograding. The included autograder has a number of options. You can view them with python autograder.py --help
Some commonly used options are: |
|
Part 1: Value Iteration (35 points)
Part 1 is concerned with Value Iteration. Now would be a good time to review the Bellman equations. You can test your Part 1 implementations with python autograder.py -p p1 Q1: Value Iteration (25 points)
In
def value_iteration(
        mdp: tm.TohMdp, v_table: tm.VTable
) -> Tuple[tm.VTable, tm.QTable, float]:
Before you write any code, it would be a good idea to take a look at the
You can test your implementation with python autograder.py -q q1
The autograder will display your value iteration process for a sample TOH MDP. You might
notice that the autograder logs lots of additional info. You can suppress this by setting
LOGLEVEL=WARNING python autograder.py -q q1 Note: Our reference solution takes 12 lines. Q2: Extracting a Policy (10 points)
In
def extract_policy(
        mdp: tm.TohMdp, q_table: tm.QTable
) -> tm.Policy:
You can test your implementation with python autograder.py -q q2 The autograder will display your value iteration process for a sample TOH MDP as well as the policy during each iteration. You can observe how the policy changes as the values change. Finally, the autograder will simulate an agent’s movement using your extracted policy. If your implementation is correct, your agent mostly follows the optimal trajectory. You can view the optimal path by selecting “MDP Rewards” → “Show golden path (optimal solution)”. Note: Our reference solution takes 2 lines. |
|
Part 2: Q-Learning (70 points)
You can test your Part 2 implementations with python autograder.py -p p2 For each of Q5 through Q8, half of the points come from quick checks of your functions (described with each question), and the other half come from a Q-learning run that uses them. Unless stated otherwise, these runs use the 3-disk MDP with 20% noise and a discount factor of 0.9, and you receive full credit for the run if your agent learns the optimal policy on the solution path (it’s OK if the policy for other states is suboptimal). Q3: Q-Update (20 points)
Q-learning performs an update on the Q-value table upon observing a transition, which in
this case is represented as an (s, a, r, s′) tuple.
Implement the
def q_update(
        mdp: tm.TohMdp, q_table: tm.QTable,
        transition: Tuple[tm.TohState, tm.TohAction, float, tm.TohState],
        alpha: float) -> None:
You can test your implementation with python autograder.py -q q3 Note: Our reference solution takes 5 lines. Q4: Extracting a Value Table from a Q-Value Table (10 points)
Q-learning only works with the Q-value table, but sometimes it is useful to know the
(estimated) value of a state. Implement the def extract_v_table(mdp: tm.TohMdp, q_table: tm.QTable) -> tm.VTable: You can test your implementation with python autograder.py -q q4 Note: Our reference solution takes 2 lines. Q5: ε-Greedy Action Selection (10 points)
At the core of Q-learning is the exploration strategy, and ε-greedy is a commonly
used baseline method. In this assignment, your agent performs active
reinforcement learning: it chooses its own next action while acting and learning, instead
of passively learning by observing a sequence of transitions chosen by someone else.
Implement
def choose_next_action(
        mdp: tm.TohMdp, state: tm.TohState, epsilon: float, q_table: tm.QTable,
        epsilon_greedy: Callable[[List[tm.TohAction], float], tm.TohAction]
) -> tm.TohAction:
Make sure you use the supplied
Pass You can test your implementation with python autograder.py -q q5 The autograder will first check your implementation on a set of Q-value tables, and then use it to run 10,000 Q-learning steps with ε = 0.2. Note: Our reference solution takes 4 lines. Q6: Custom Epsilon (10 points)
If you use a constant ε, your agent will keep wasting time exploring unnecessary
states long after it has learned a good policy. A common way to mitigate this is to make
ε a function of the time step that decreases over time. For example, see the
“How to Explore?” slide in our
Q-Learning lecture slides, or, for more
detail, slides 44–46 on GLIE: Greedy in the Limit with Infinite Exploration
in this PowerPoint
presentation (UW sign-in required).
Implement def custom_epsilon(n_step: int) -> float:
Your
To activate your custom epsilon schedule, set python autograder.py -q q6 As in Q5, the autograder will then use your custom ε function to run 10,000 Q-learning steps. Note: Our reference solution takes 1 line. Q7: Exploration Function (10 points) While ε-greedy Q-learning uses randomness to control exploration, it is also possible to guide exploration more systematically. One way to do this is with “exploration functions” that give the agent an incentive to explore parts of the state space that have not been visited as much as others. (See the “Exploration Functions” slide, slide 19, in the Q-Learning lecture slides.)
Implement two functions in def exploration_fn(u: float, n: int) -> float:
We strongly recommend this form, which uses a slowly decreasing bonus:
The lecture slides (adapted from UC Berkeley's CS 188) show a simpler and more intuitive
form,
Whatever form you use, the autograder checks that, for a fixed Then implement the action-selection function that uses it:
def choose_next_action_with_exploration_fn(
        mdp: tm.TohMdp, state: tm.TohState, q_table: tm.QTable,
        visit_counts: Dict[Tuple[tm.TohState, tm.TohAction], int],
        exploration_fn: Callable[[float, int], float]
) -> tm.TohAction:
This function should pick the action that maximizes
You can test your implementation with python autograder.py -q q7
The autograder will check
Note: Our reference solution takes 1 line for Q8: Custom Alpha, the Learning Rate (10 points) Design and implement a scheme for gradually lowering the value of α (the learning rate) that is used in the Q-update formula. The purpose of starting with a relatively high value (close to 1) and gradually lowering it is to obtain plausible Q-value estimates quickly (rather than the zeros with which they were initialized), but, over time, to reduce the influence of each new sample, since giving new samples a lot of influence makes the Q-updates “forget” the samples further back in time. def custom_alpha(n_step: int) -> float:
Your
To activate your custom alpha schedule, set python autograder.py -q q8 As in Q6, the autograder will then run 10,000 Q-learning steps (with ε = 0.2) using your custom alpha schedule. Note: Our reference solution takes 1 line. |
|
Part 3: Report (40 points)
Q9: Report (40 points)
The starter code includes a file The template has four parts plus a partnership retrospective:
Part B questions (40 points total):
|
|
What to Turn In
Turn in the following two files to Gradescope, in the assignment “A5”: solver_utils.py a5_report_firstname_lastname.txt Before submitting, you can run the entire local test suite with python autograder.py
Partnerships.
If you are in a partnership, do the following: (1) fill in the partnership comment at the
top of # Partnership? YES # Submitting partner: John Doe # Other partner: Jane Smith
(2) when you submit to Gradescope, indicate that this is a group submission and add
your partner, and (3) complete the partnership retrospective in your report.
If you are working alone, write |
| Updates and Corrections
If needed, updates and corrections will be posted here, and/or in ED. |
| Last updated 2026-11-06. |